

Overview
The Modeler is where a simulation model gets built: a directed graph of components on a canvas, plus the entities, expressions, reference data, and event logic that make it behave like your operation. This page is the working reference for that surface — the controls at the top of the page, every component type and its configuration, the expression language, the left panel, and how a model actually runs.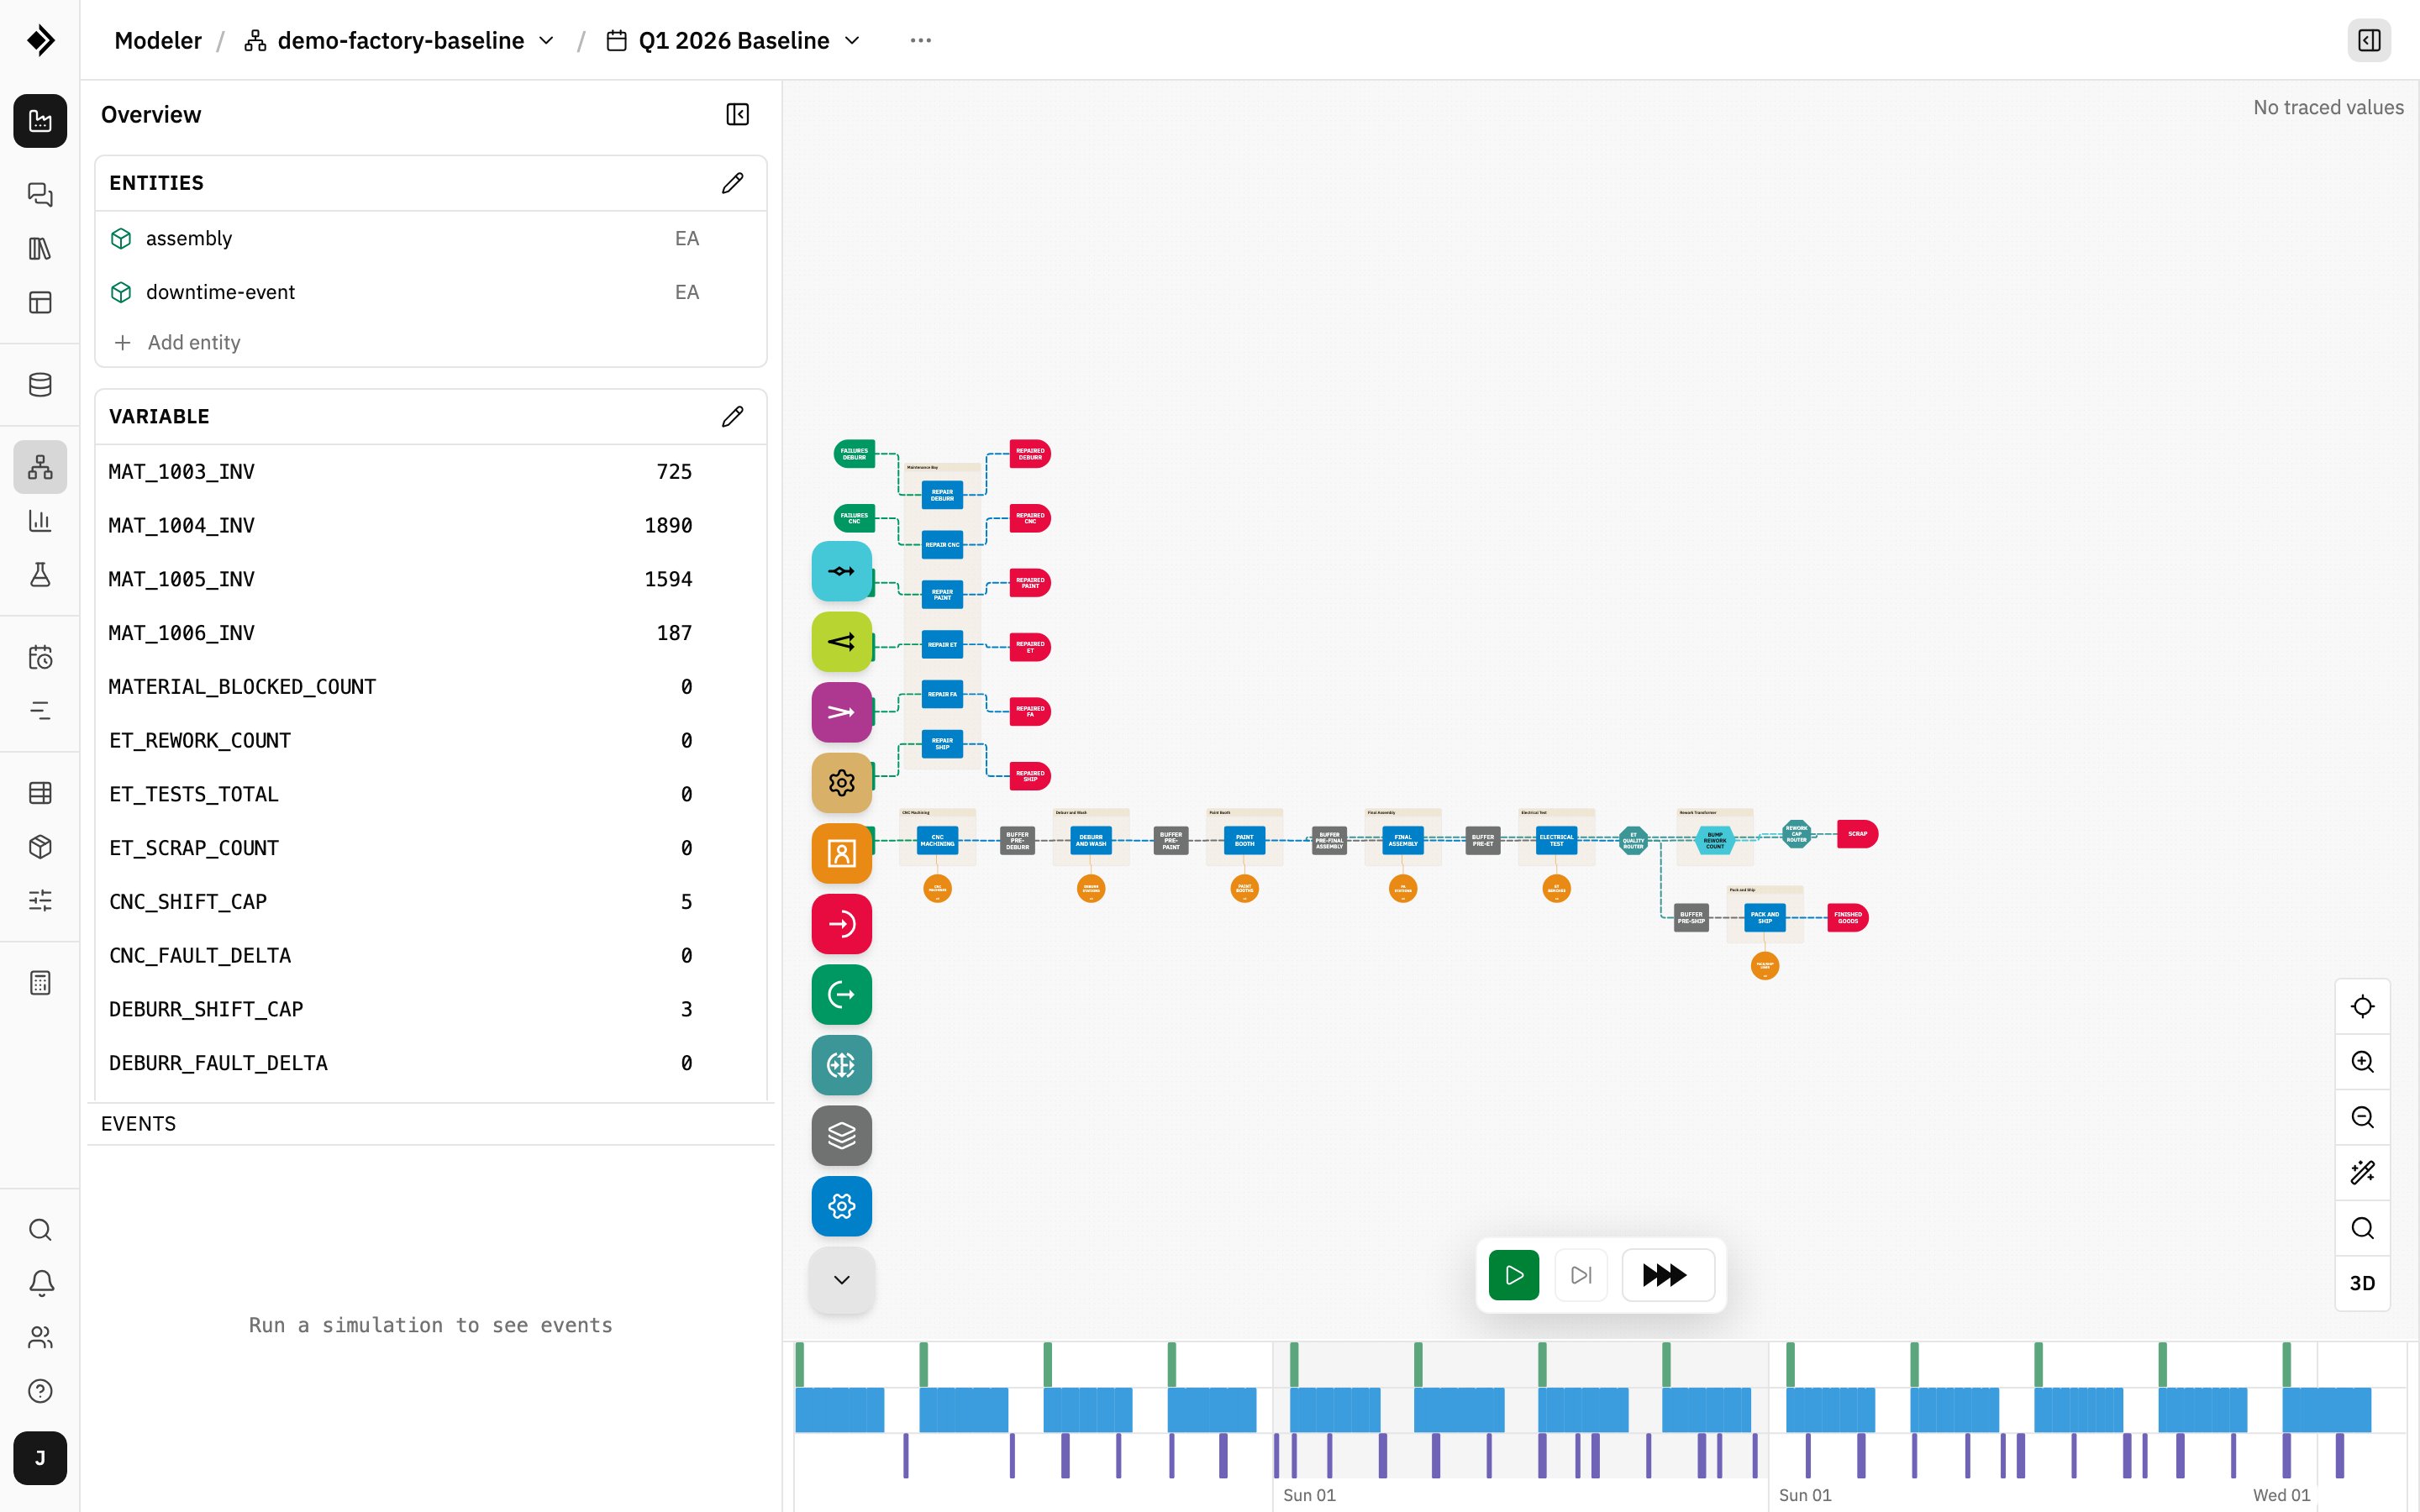
The Modeler: the Overview panel, the component dock and the canvas
What discrete event simulation is
Discrete event simulation (DES) represents an operation as a sequence of instants at which something changes — an order arrives, a machine finishes a cycle, a resource frees up. Between events nothing happens, so simulated time jumps from one event to the next; that’s why a model of a month of production runs in seconds. Change a capacity, a distribution, or a buffer and you see the downstream effects immediately, without touching the real system. You build the model visually and ProDex’s simulation engine executes it directly. The canvas is the source of truth — there is no engine code to write.Building on the Canvas
A model is a directed graph: components are nodes, connections are edges, and entities flow along the edges. Drag components from the dock in the canvas’s bottom-left corner (the arrow button beneath it expands and collapses it), drop them on the canvas, wire each component’s output handle to the next component’s input handle, and click any component to open its settings in the left panel’s Properties view. The minimum viable model is Source → Process → Sink. Everything else — buffers, routers, stations, event logic — earns its place as your questions demand it.The Top Bar
- Model picker — switches the open model; its menu also holds New Model, Rename, and Delete.
- Schedule picker — picks what drives timing: Default (no schedule) or any schedule defined for the model. Its menu also holds New Schedule, plus Edit and Delete for the selected schedule. With a named schedule active, the schedule’s own Start and End Times drive the run.
- Duration — shown while Default is the active schedule; sets the run length (
DDD:HH:MM:SS). - Resource fill rule — how Processes compete for Resources when a request can’t be met yet. See Resource fill rule.
Component Types
Every flow component’s panel also carries an Event Hooks and an Event Listeners section — the reaction logic covered in The Event System below.Source
Where entities enter the model.- Entity type — which entity this Source produces.
- Arrival logic — the inter-arrival time (time between arrivals, not a rate), drawn from the distribution picker or a DSL expression.
- Initial attribute values — per attribute, a Strategy: Fixed, DSL Expression, Round Robin, Random (pick from the attribute’s choices), Distribution (sample a distribution), or Weighted (a value/weight table). The dropdown narrows to the strategies valid for the attribute’s type — see the type-by-strategy matrix. Note that a DSL assignment at a Source runs before the entity exists, so it can’t read the new entity’s other attributes.
- Events — fires entity created per produced entity.
Process
A step that takes time and may consume resources.- Entity Type — scopes the rest of the panel to one entity type.
- Processing time — a distribution or DSL expression.
- Resource requirements — a multi-row table (Add Row) of resource → whole-number quantity. Connecting a Resource node to one of the orange resource handles on the top or bottom of the Process adds a row too; a connection to the Process’s side flow handles does not. Each row’s Hold switch keeps that resource with the entity after this process, so the next process that needs it uses it without a new request. Ask Dexter to make a quantity an expression; a requirement whose quantity evaluates to 0 is skipped for that entity — the mechanism behind cross-training and substitution patterns.
- Station — optionally places the Process inside a Station.
- Events — process started, process completed.
Resource
A capacity pool — workers, machines, fixtures — that Processes draw from. Drag a Resource from the dock like any other component, then connect it to an orange resource handle on each Process that uses it (or pick it in the Process’s requirement table).- Capacity — number of parallel slots.
- Allocation Discipline — FIFO, LIFO, or Priority (a DSL key with ascending/descending ordering).
- Changeover Times — a table of (from process, to process) → duration rows. Same-process pairs are allowed. In the panel each duration is a fixed time; ask Dexter when a changeover should be a distribution or a DSL expression. An expression can read the changeover-only identifiers for the exiting and entering entities — their types and their attributes — so a single changeover time can vary with the (exiting entity, entering entity) pair rather than being keyed only by process.
- Events — slot freed, slot working. A set capacity action reacting to shift topics is the standard shift scheduling pattern; the same mechanism models breakdowns, maintenance windows, and staffing changes.
Changeover keys are processes, not entity types. A resource that handles two products through the same process incurs no changeover; switching between two processes (even on the same entity type) does. If your changeover model is keyed by entity type today, rework it around the processes that actually demand the setup.
Resource fill rule
A Process acquires everything it needs at once: it starts only when every resource in its requirement table has a free slot, and while it waits it ties up nothing beyond resources the entity is already holding from an earlier process. Each Resource ranks the waiting requests by its Allocation Discipline. The Resource fill rule in the ⋯ menu decides what happens when the request at the front of the line can’t be met yet:- Allow bypass (pass) — the default. A request that can get all its resources may go ahead of a blocked one.
- Preserve precedence (no pass) — blocked requests keep their place in the queue, even if that leaves free capacity idle.
Buffer
A waiting area between components.- Entity Type, and Capacity with an explicit Infinite toggle.
- Queue Discipline — FIFO, LIFO, or Priority.
- Release Mode — Push (auto-release) sends entities downstream as soon as there’s room; Hold (manual release) keeps them until a release action fires — the kanban/pull pattern.
- Events — entity entered, entity exited, contents changed. Buffers and Stations are the components that emit the per-entity entered/exited pair; Processes signal through process started/completed instead.
Router
Splits entity flow across outgoing connections based on its Logic Type:
Routers fire entity routed per entity. Each Conditional or Probabilistic rule row has a See expression / AI explanation toggle that flips between the raw DSL and a plain-English explanation — the fastest way to confirm a rule does what you think it does.
Combiner, Separator, and Transformer
The batching components, covered in depth in Combiners, Separators & Transformers:- Combiner — merges multiple inputs into one output (assembly). Batches form either from static per-input quantities or from a dynamic batch expression evaluated on each arrival. Output attribute assignments run in multi-entity context, so aggregations apply —
SUM,MEAN,MAX,MIN,COUNT,ANY,ALL,MODE,N_UNIQUEover the batch (e.g.SUM(weight),MAX(priority),ALL(qc_passed)). An aggregated attribute must exist on every input type — give a default to inputs that don’t naturally carry it rather than leaving it absent. - Separator — splits one input into several outputs: an Output Batch table pairs each output entity type with a count expression, with per-output attribute assignments (Fixed or DSL).
- Transformer — one in, one out. Changing the entity type is only half its job: configuring the same input and output type is the standard way to mutate attributes mid-flow (incrementing a rework counter, stamping a QC result).
Station
A capacity-constrained container representing a physical space or work center. Capacity is a per-entity-type table (e.g., Tube = 500, Tray = 100), so one station can hold different quantities of different items at once; leave a type unbounded when the station isn’t the constraint. Stations also group related components, which keeps large models navigable — and emit entity entered, entity exited, and contents changed (multi-entity context over the current contents, the usual seat of WIP gauges).Sink
The exit point. Entity Type is required — only matching entities may enter — and entities that arrive are consumed, counted, and fire entity terminated.Model Node
Embeds another model from the same factory as a single component — the key to hierarchical modeling. First import the model: in the left panel’s Sub-models section, click + (or Import Model) and pick another model in the factory. Imported models then appear under the dock’s Sub-model button; open it and drag a model onto the canvas. Each instance maps its outer connections to the sub-model’s internal sources and sinks, and can alias resources, topics, and state variables per instance; nested components are addressed withparent::child qualified paths. See Model Nodes & Hierarchical Modeling.
Connections
Drag from a component’s output handle to another’s input handle to define flow. Entities move along a connection when the downstream component can accept them — or, for Hold-mode Buffers, when explicitly released. Two topology rules worth knowing up front: connections can’t start or end at a Station (wire the components inside it instead), and a Router’s rules attach to its outgoing connections. Validation enforces the full ruleset as you edit.The Event System
Flow connections describe how entities move; the event system describes how the model reacts. Two primitives, both configured on every flow component’s panel:- Event Hooks fire on the component’s own lifecycle events — the entity created / process completed / contents changed events listed per component above. The hook’s expression context follows the event: single-entity for per-entity lifecycles, multi-entity for batch and contents-changed events, no-entity for resource slot events.
- Event Listeners fire when a subscribed topic is emitted anywhere in the model — and always run in no-entity context: a listener can read state variables, constants, lookups, and component queries, but never the emitting entity’s attributes. When cross-component logic needs per-entity data, the pattern is: a hook writes what it needs into state and emits; the listener reads state.
Expressions and the DSL
Most numeric and logical fields accept either a literal or an expression in ProDex’s DSL, which is how models become dynamic and data-driven: routing conditions over attributes, per-entity resource needs, durations that depend on state. Identifiers available everywhere:SIM_TIME (current simulation time) and SIM_DURATION (the configured run length, not the time remaining). In entity contexts: ENTITY_TYPE (the entity’s type slug) and ENTITY_AGE. In hooks and listeners: SELF, the hosting component’s id — which makes rules copy-pasteable across components.
Component queries, usable in every context: BUFFER_LEVEL(id), BUFFER_CAPACITY(id), RESOURCE_AVAILABLE(id), RESOURCE_CAPACITY(id), STATION_WIP(id) — and LOOKUP(table, key1, key2, ..., default:=value) reads a lookup table by one or more keys.
Which fields run in which context — and the full catalog of functions and aggregations — lives in The Expression Language.
Distributions are picked from a ten-option dropdown (Fixed, Normal, Exponential, Uniform, Lognormal, Weibull, Triangular, Erlang, Beta, Gamma), not written as DSL calls. Every parameter of every distribution accepts a literal number or a per-sample DSL expression, so any of them can vary by entity or state. See Distributions for parameter conventions and which to reach for.
The Left Panel
The panel to the left of the canvas has two views:- Overview — what the model uses, in six sections: Entities, Variable, Topics, Constants, Lookup tables, and Sub-models. Each section’s header pencil (View and manage all) opens the full management dialog, and the + Add … row at the bottom of a section adds an existing item to the model or creates a new one (Sub-models use the header + instead). A row’s × removes the item from this model without deleting it; it’s disabled while something in the model still references the item. Below the sections, an Events list fills in as a simulation runs, and during replay the Variable rows show live values.
- Properties — the settings of the component you’ve selected on the canvas. The back arrow returns to Overview.
Entities
The items that flow through your simulation: raw materials, WIP, finished goods. An entity type must be added to the model before a Source, Transformer, or other component can use it — use + Add entity in the Entities section, or open the pencil to create, edit, and browse entity types and click Add to model. Each entity type carries typed attributes (Boolean, Number, Text, Text List, Number List), referenced by bare name in single-entity contexts — noself. prefix. Attributes persist with the entity through the whole flow. Note that the two list types are discrete choice sets — despite the name, each holds a single member of its declared choices, not a collection. They accept only a fixed or sampled value; a DSL-computed assignment is rejected in validation. If a downstream node needs to compute or thread the value, make the attribute a scalar Number or Text instead.
Constants
Named, factory-scoped parameters — Text, Number, or Boolean — referenced by bare name in any expression:PROCESSING_TIME_MINUTES * SHIFT_EFFICIENCY_FACTOR. Names must be SCREAMING_SNAKE_CASE and can’t reuse a reserved word or the name of another constant or lookup table. Constants are the right home for any value that appears in several places or that you’ll vary between runs: change it once, and every referencing field updates.
Lookup Tables
Keyed tables queryable from any expression —LOOKUP(CYCLE_TIMES, ENTITY_TYPE) — with SCREAMING_SNAKE_CASE names, one or more key columns and Text/Number/Boolean values. A missing key returns the default:= you pass, or a type-specific zero (0, "", FALSE) if you don’t. Typical uses: cycle time by product, yield by material, routing weight by order class. See Constants & Lookup Tables.
State Variables
Model-level mutable values that persist across entities: current shift, an inventory level, a rolling average. Read them by bare name in any context; write them with an assign action on a hook, listener, or scheduled action. Names follow the same SCREAMING_SNAKE_CASE rule. Use a state variable when the value belongs to the system; use an entity attribute for per-entity data.Topics
Named pub/sub channels: a component publishes with an emit action, and any component whose Event Listener subscribes to the topic reacts — coordination without a flow connection between them. Constants, Lookup Tables, State Variables, and Topics share one four-tab Lookups dialog; the pencil on the matching Overview section opens it on that tab.Schedules
A model runs in abstract time until you pair it with a schedule, which anchors execution to wall-clock time: material releases inject specific entities at specific moments (in parallel with Source arrival logic, not instead of it), and scheduled actions fire assign and emit at specific times — the component-control actions remain hook-only. A model can hold multiple schedules — baseline week, stress scenario, historical replay — and you pick the active one in the schedule picker at the top of the page.Running a Simulation
The run controls sit at the bottom of the canvas:- Run simulation (play button) — executes the model to completion.
- Fast forward to end (skip-forward icon) — jumps the on-canvas playback straight to the end of the run; available once a run has produced data to replay.
- Playback speed — controls the on-canvas animation only. The engine always runs at full speed.
⌘F / Ctrl+F), and 3D.
3D view
3D (or theV key) switches the canvas to a 3D shop-floor view of the same model; 2D view, or V again, switches back. The dock, run controls, and component selection all work in 3D. Left-drag to orbit, hold Space or right-drag to pan, scroll to zoom, and Shift-drag to select several components. The Modeler remembers which view you last used for each model.
Tips and Best Practices
- Start simple. Source → Process → Sink validates your setup before you add complexity.
- Use constants for anything you’ll change between runs — scenario sweeps become one-field edits.
- Name everything in the operator’s terms. Component names surface in results, event logs, and charts; good names pay off every time you read output.
- Use stations to group related components — large models get hard to navigate without structure.
- Watch the play button. Green means valid; red names a specific blocker, and Fix with Dexter hands it to Dexter.
- Copy before big changes. Ask Dexter to copy the model at milestones, so you can still run the earlier configuration to compare against.